


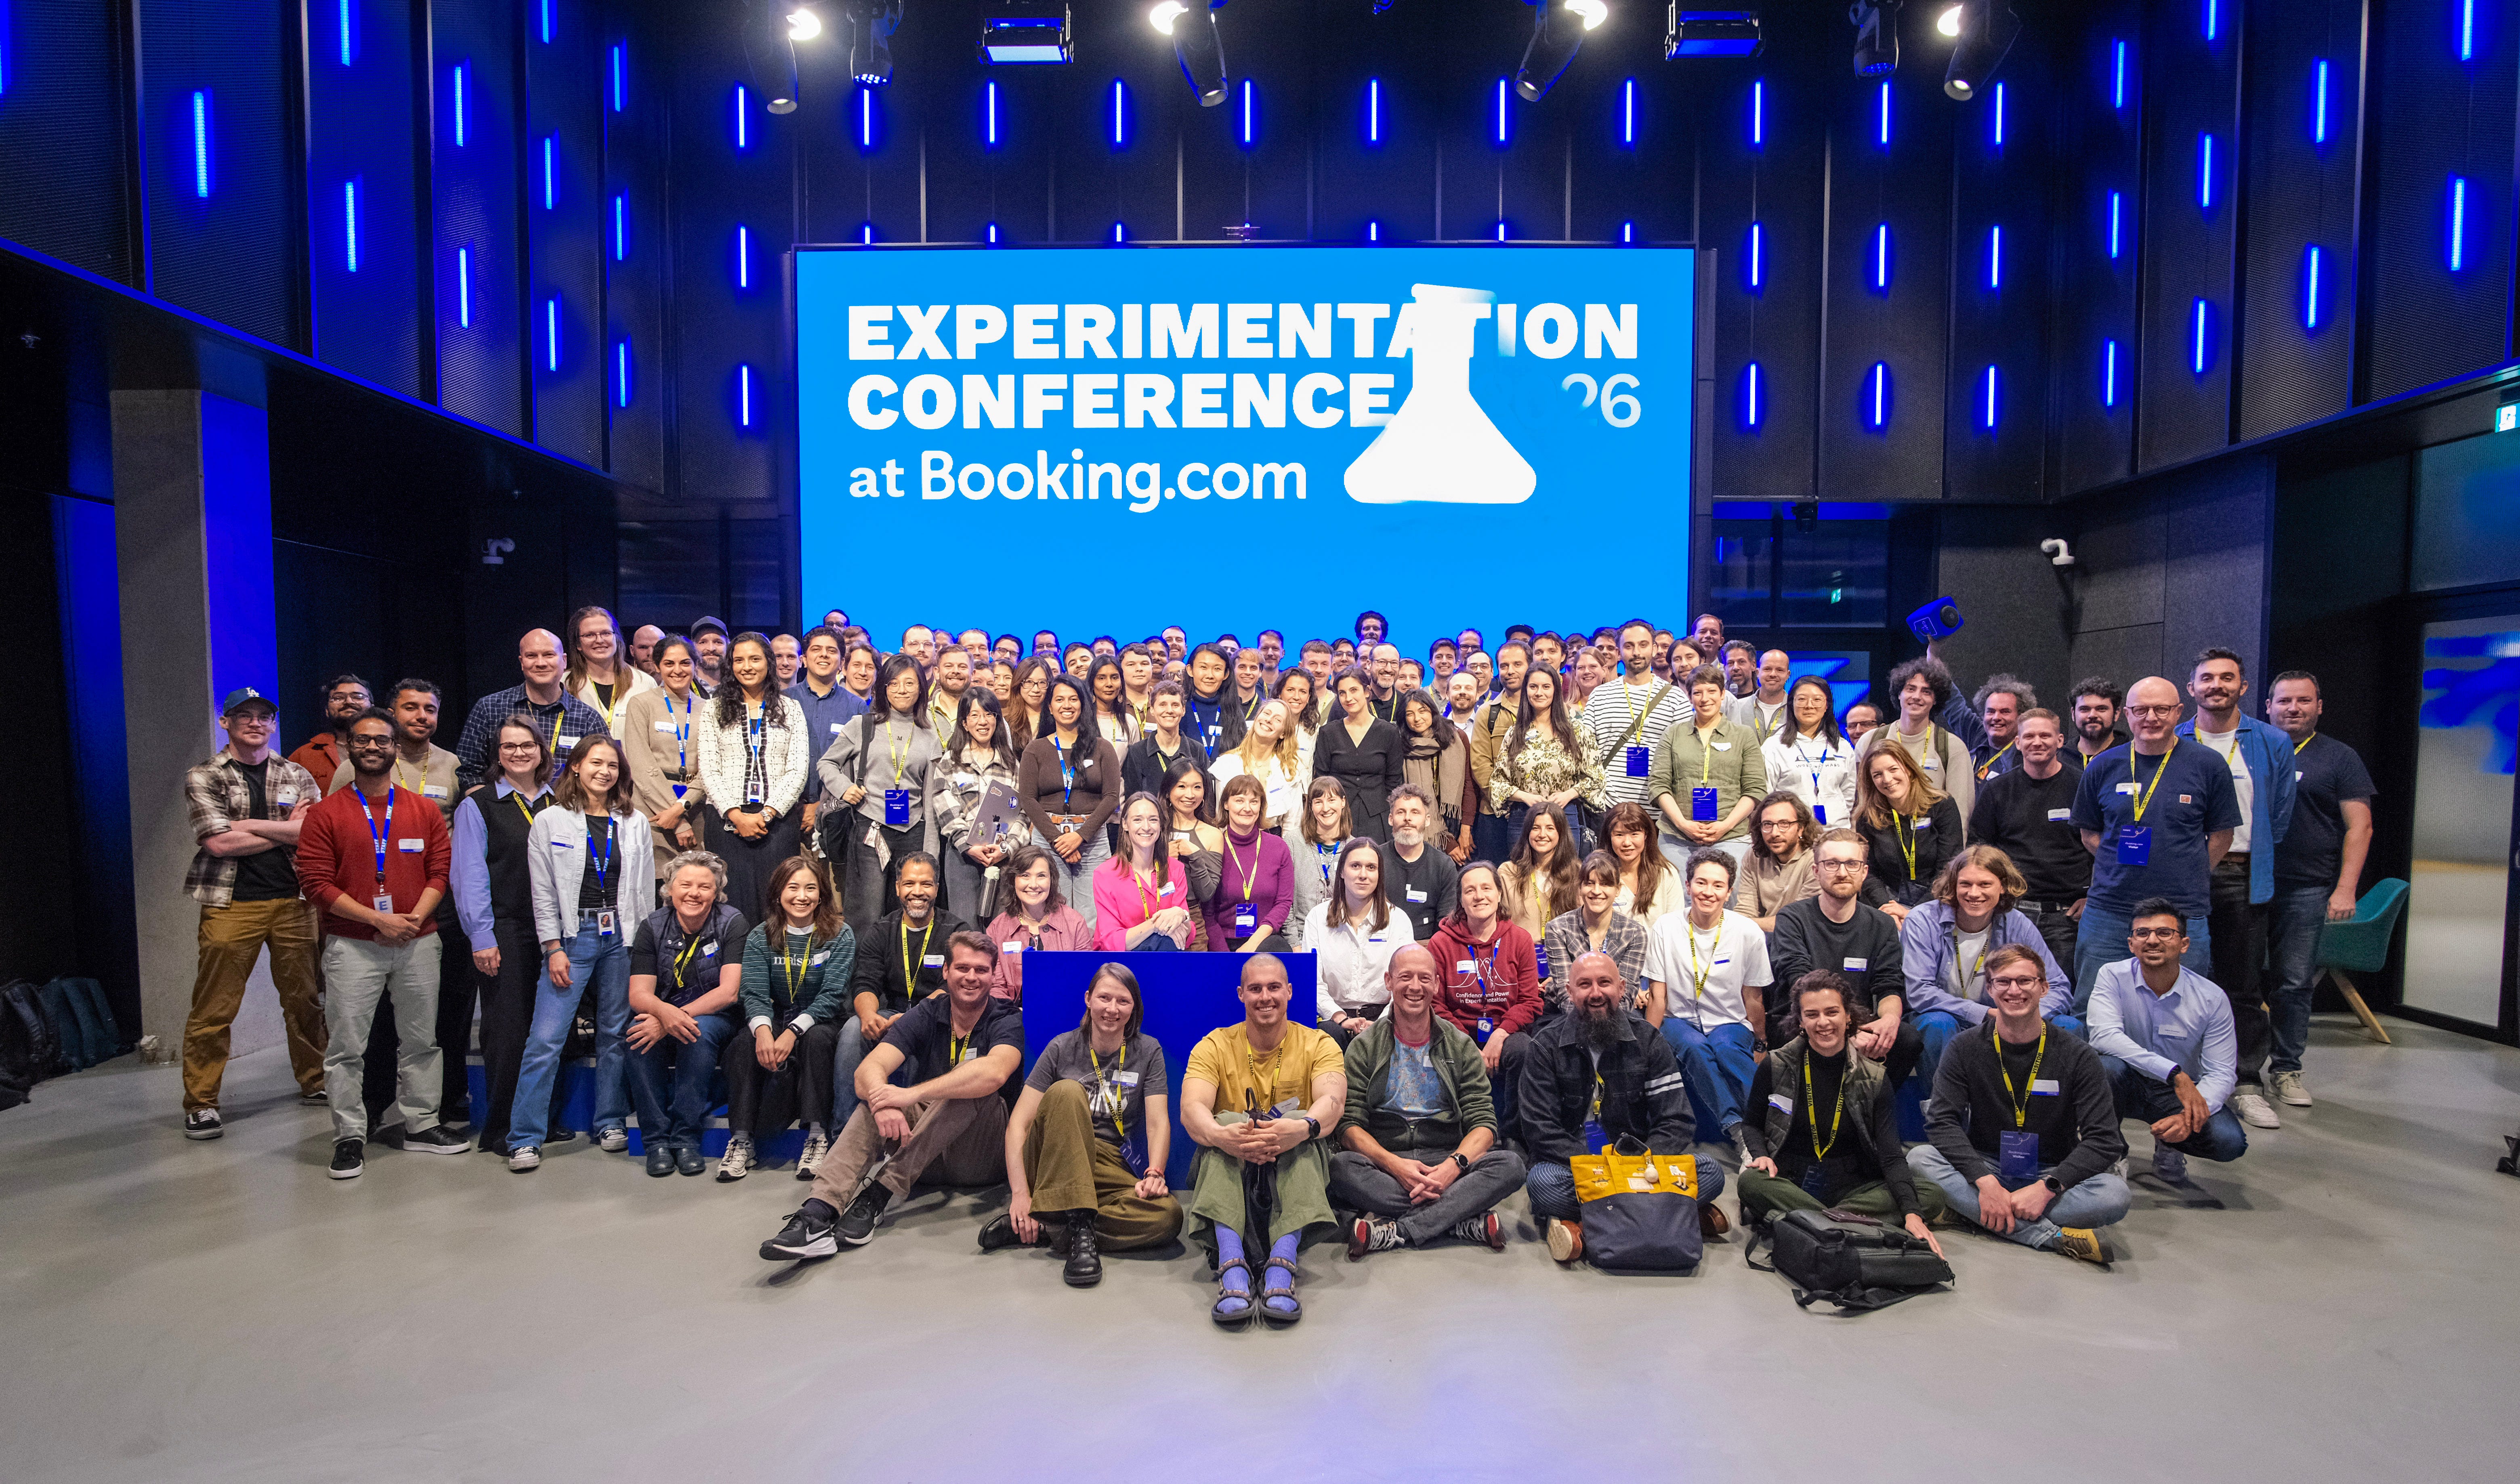
On May 18, 2026, we hosted the third annual Experimentation Conference at Booking.com on our Amsterdam campus. What started in 2024 as an experiment itself — would large-scale experimentation practitioners come together to learn from each other? — has grown into an event which brings together over 150 practitioners from 49 companies which run experiments at scale. About one third of attendees came back a second or third time. The room collectively ran 56,000 experiments per year. It’s a unique crowd, and that’s exactly the point.
The day opened with sharing the results of the survey data we collected from the participating companies on the state of experimentation across the room, revealing some interesting findings:
most teams operate a centre of excellence model,
roughly a third release over 90% of features through controlled experiments,
and the top challenges are scaling, coordination, platform tooling, and culture.
These shared experiences helped shape the programme.
We had three sessions, grouped by the three conference themes:
AI and experimentation: AI-assisted analysis, no-code experimentation
Quality / velocity tradeoff: High-quality vs high-speed experimentation
Experimentation culture: Build organizational buy-in and data-driven decision-making
Each session followed the same format: two talks, then a panel discussion on the same topic. We closed with nine parallel breakout groups for deeper conversation. Below is a recap of the key sessions.
Read the recap of 2025 | Read the recap of 2024
Session 1: AI and experimentation
The conference started off with the hot topic of AI in experimentation. AI is changing how we experiment and how we support experimenters.
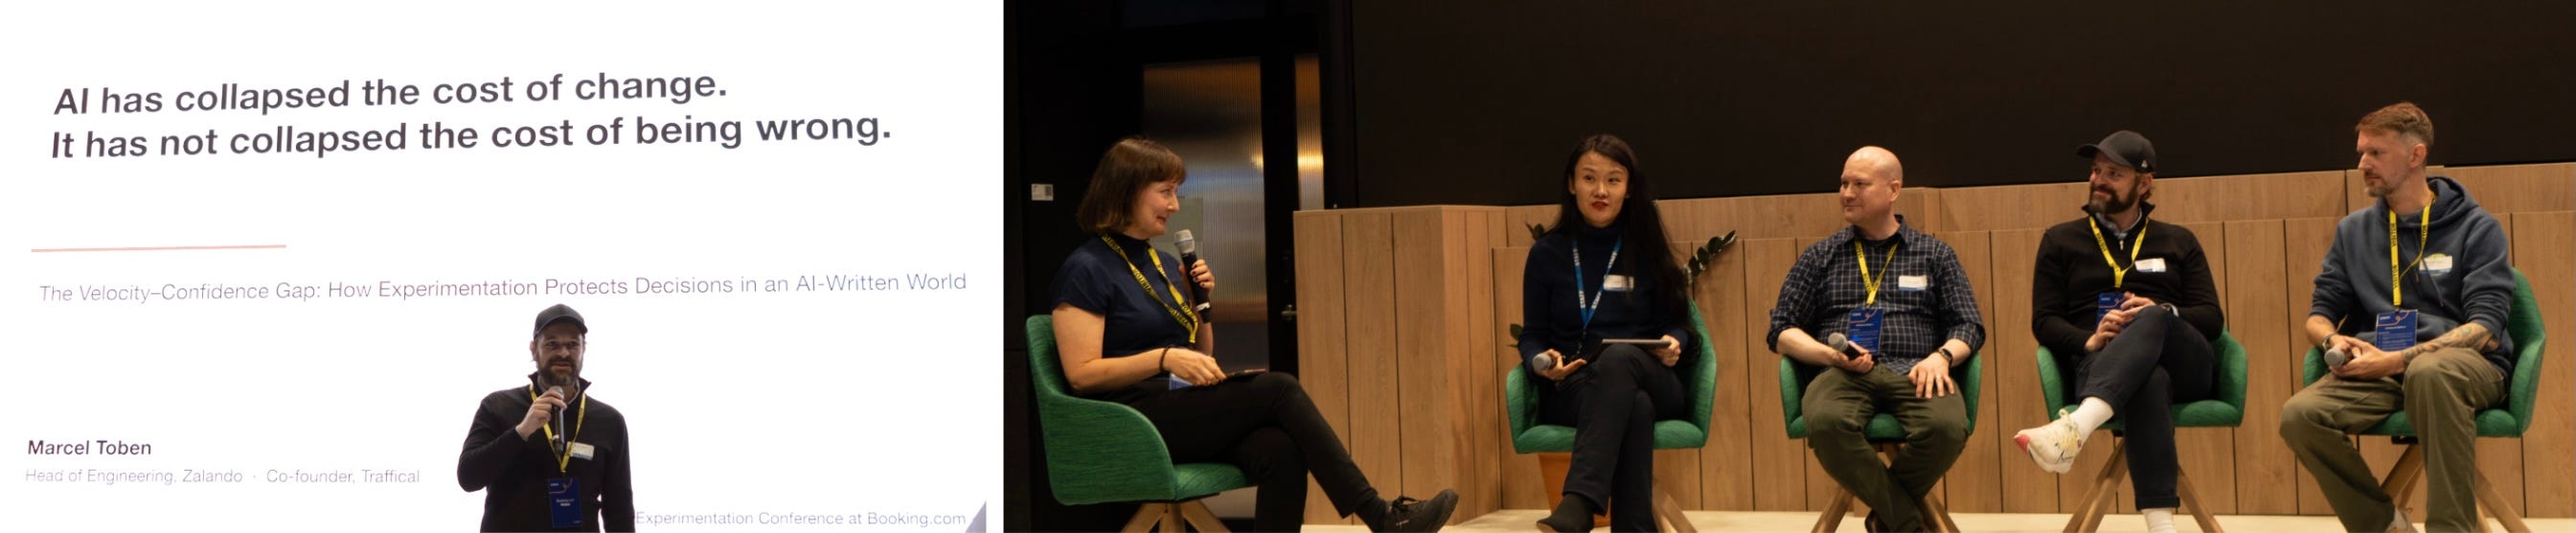
How Experimentation Protects Decisions in an AI-Written World — Marcel Toben
Marcel Toben, Head of Engineering at Zalando, opened with a provocation he’d recently heard from software engineers in Berlin: nobody on his team had written code by hand in months. The inner loop of development (ideate, prototype, code, review, deploy) is closing fast. Agents are handling pull requests while engineers sleep. But Marcel’s argument was that this acceleration makes the outer loop (rollout, monitor, experiment, optimize, decide) more important, not less. If this outer loop does not scale at the same pace, teams end up shipping more decisions they can’t defend.
His proposed answer is a “control plane for change”: a unified layer combining certified metrics, consistent assignment, progressive rollout, guardrails, and a decision log. All designed to be traversable by both humans and agents. He also introduced Zalando’s shift from feature flags to parameters: continuous, centrally governed values that allow agents to run experiments, tune configurations, and adaptively optimize within human-defined constraints. Four things, he argued, stay with humans: strategy, craft, ethics, and decisions made in the absence of clear evidence.
Key takeaway: AI has collapsed the cost of change. It has not collapsed the cost of being wrong. Build the infrastructure that lets you tell what actually happened when you shipped.
Building an Experimentation Knowledge Base — Dima Bordiugov
Dima Bordiugov, a Product Data Scientist at Delivery Hero, tackled a different problem: how do you stop teams from re-running experiments that have already been done, and how do you let a good idea in one part of a group of eight companies reach the others?
The answer Delivery Hero landed on was a custom self-service knowledge base: experiment design documents chunked into structured sections (hypothesis, decision, rationale), embedded as vectors in BigQuery, and queried through a combination of semantic search and LLM-generated SQL. Users ask questions in natural language and get answers backed by past experiment data, with the generated SQL visible so technical users can check the reasoning. Dima’s most practical observation was that a cheap, fast model with a rich, well-structured prompt consistently outperforms a large, expensive one with a lazy prompt.
Key takeaway: Institutional knowledge doesn’t preserve itself. Structuring your experiment records for retrieval, not just storage, is what lets past learnings compound.
Session 2: Quality versus velocity
The conference continued with the classical topic of quality versus velocity. The trade-off between speed and rigour is real, but not fixed.
Opinionated Experimentation Tooling — Giacomo Mason
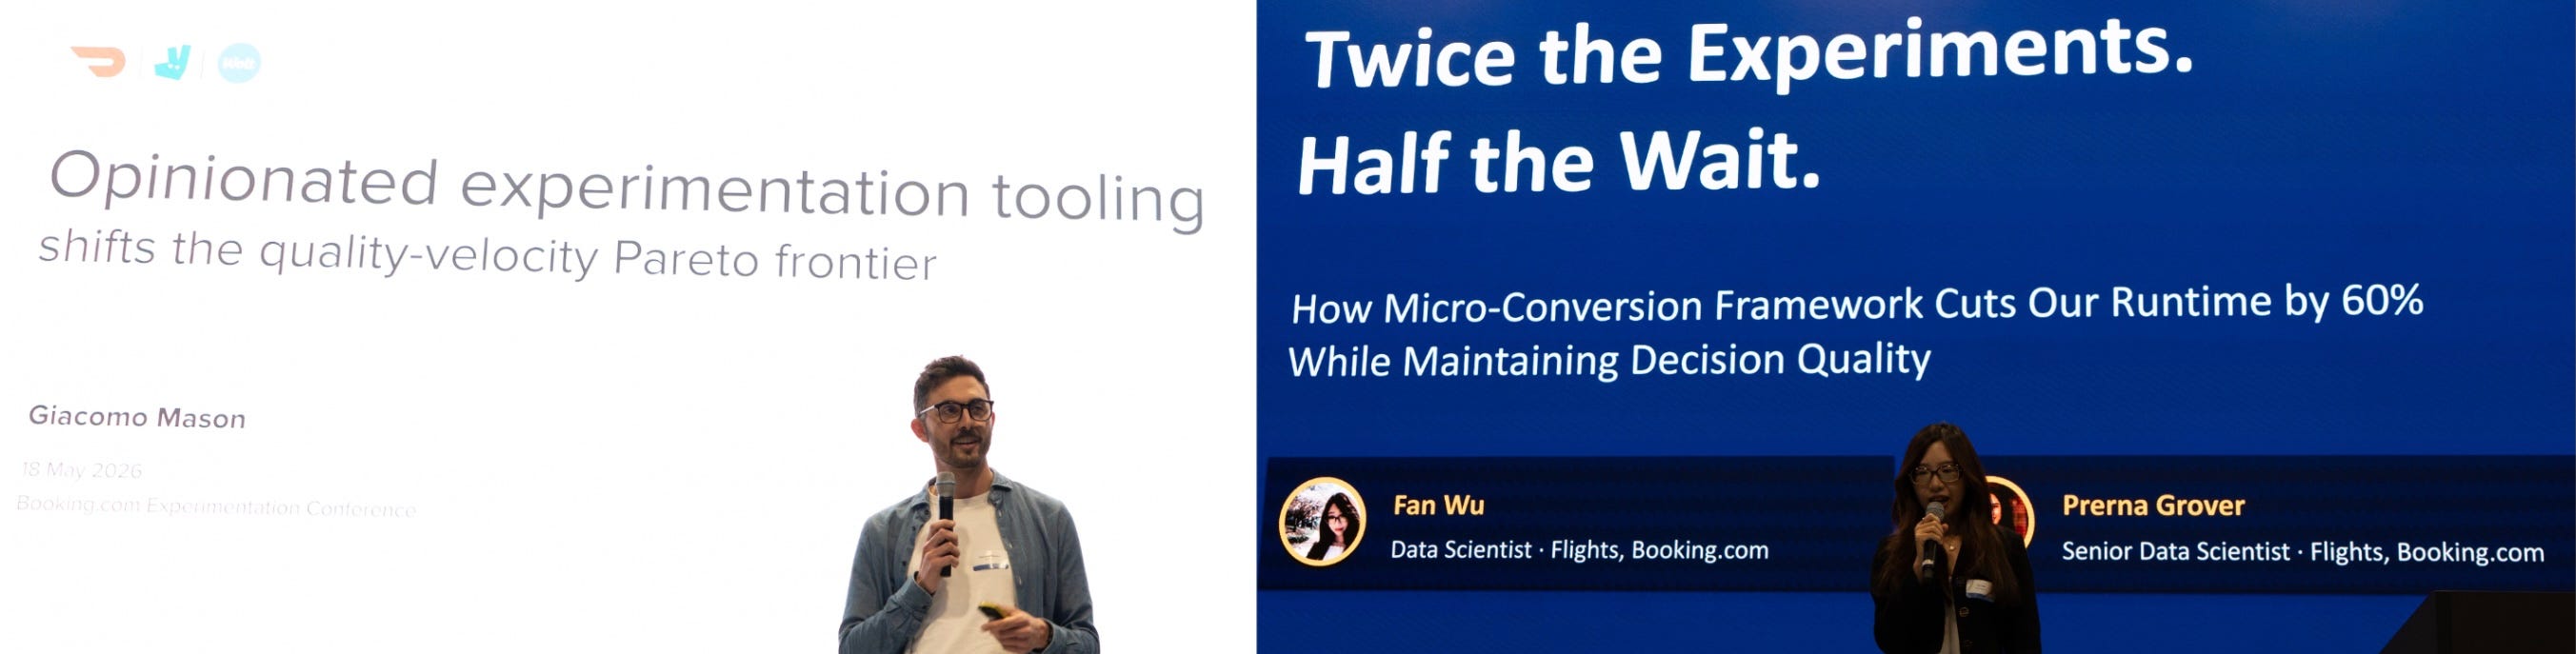
Giacomo Mason, a Staff Data Scientist at Deliveroo, built his talk around a concept from economics: the Pareto frontier. At some point you can’t get faster without sacrificing quality. But new technology can shift that frontier outward and his argument was that “opinionated tooling” is that technology for experimentation.
Opinionated tooling, as Giacomo defined it, means designing your platform to encode your organisation’s decision-making philosophy: what metrics matter, what constitutes a good experiment, and what happens when something goes wrong. At Deliveroo this takes three forms:
Base-layer statistical rigour: variance reduction, balance checks, clustering, the unglamorous stuff that any decent platform should handle.
Standardisation: mandatory guardrail metrics on every experiment, and a gatekeeper approval flow when those metrics are harmed.
Intellectual honesty: primary metrics are locked before launch and require a manual unlock to change, and testing parameters must be declared upfront.
These constraints slow down individual experiment setup. They speed up organisational decision-making significantly.
Giacomo was also clear that AI amplifies whatever opinions you’ve already embedded, it doesn’t substitute for having them.
Key takeaway: Opinions embedded in tooling become binding for the whole organisation. The friction that annoys individual experimenters is the same friction that stops bad rollouts and cherry-picked results.
The Micro-Conversion Framework — Fan Wu and Prerna Grover
Fan Wu and Prerna Grover, data scientists in Booking.com’s Flights team, shared a framework born from a specific pain: the Flights team had to run experiments for an average of 34 days to achieve sufficient power. These long experiment runtimes slowed down product development and learnings. Yes, high traffic companies can also have low traffic challenges…
Their solution was to identify earlier funnel actions, micro-conversions, that are highly correlated with the final booking but occur far more frequently. For the Flights funnel, progression from the flight detail page to checkout serves as such a proxy. The key rigour: candidate micro-conversions are validated through historical meta-analysis before adoption, the final business metric is always kept as a guardrail, and aggregate impact is confirmed through either blockouts (reverting all shipped changes for a period) or retests (rerunning a successful micro-conversion experiment to confirm conversion impact). In a pilot, average runtime dropped from 34 to 14 days, experiments per quarter rose 60%, and features shipped to 100% of users increased 250%. It’s since spread beyond Flights to customer acquisition, post-booking, and performance marketing teams.
Key takeaway: If you’re waiting too long for your final metric to move, find an earlier action that reliably predicts it — but validate the correlation and check the results with retests or blockouts.
Session 3: Experimentation culture
The final topic was experimentation culture. All technical challenges are people problems in disguise.
Why the King Needs a Jester — Lukas Vermeer
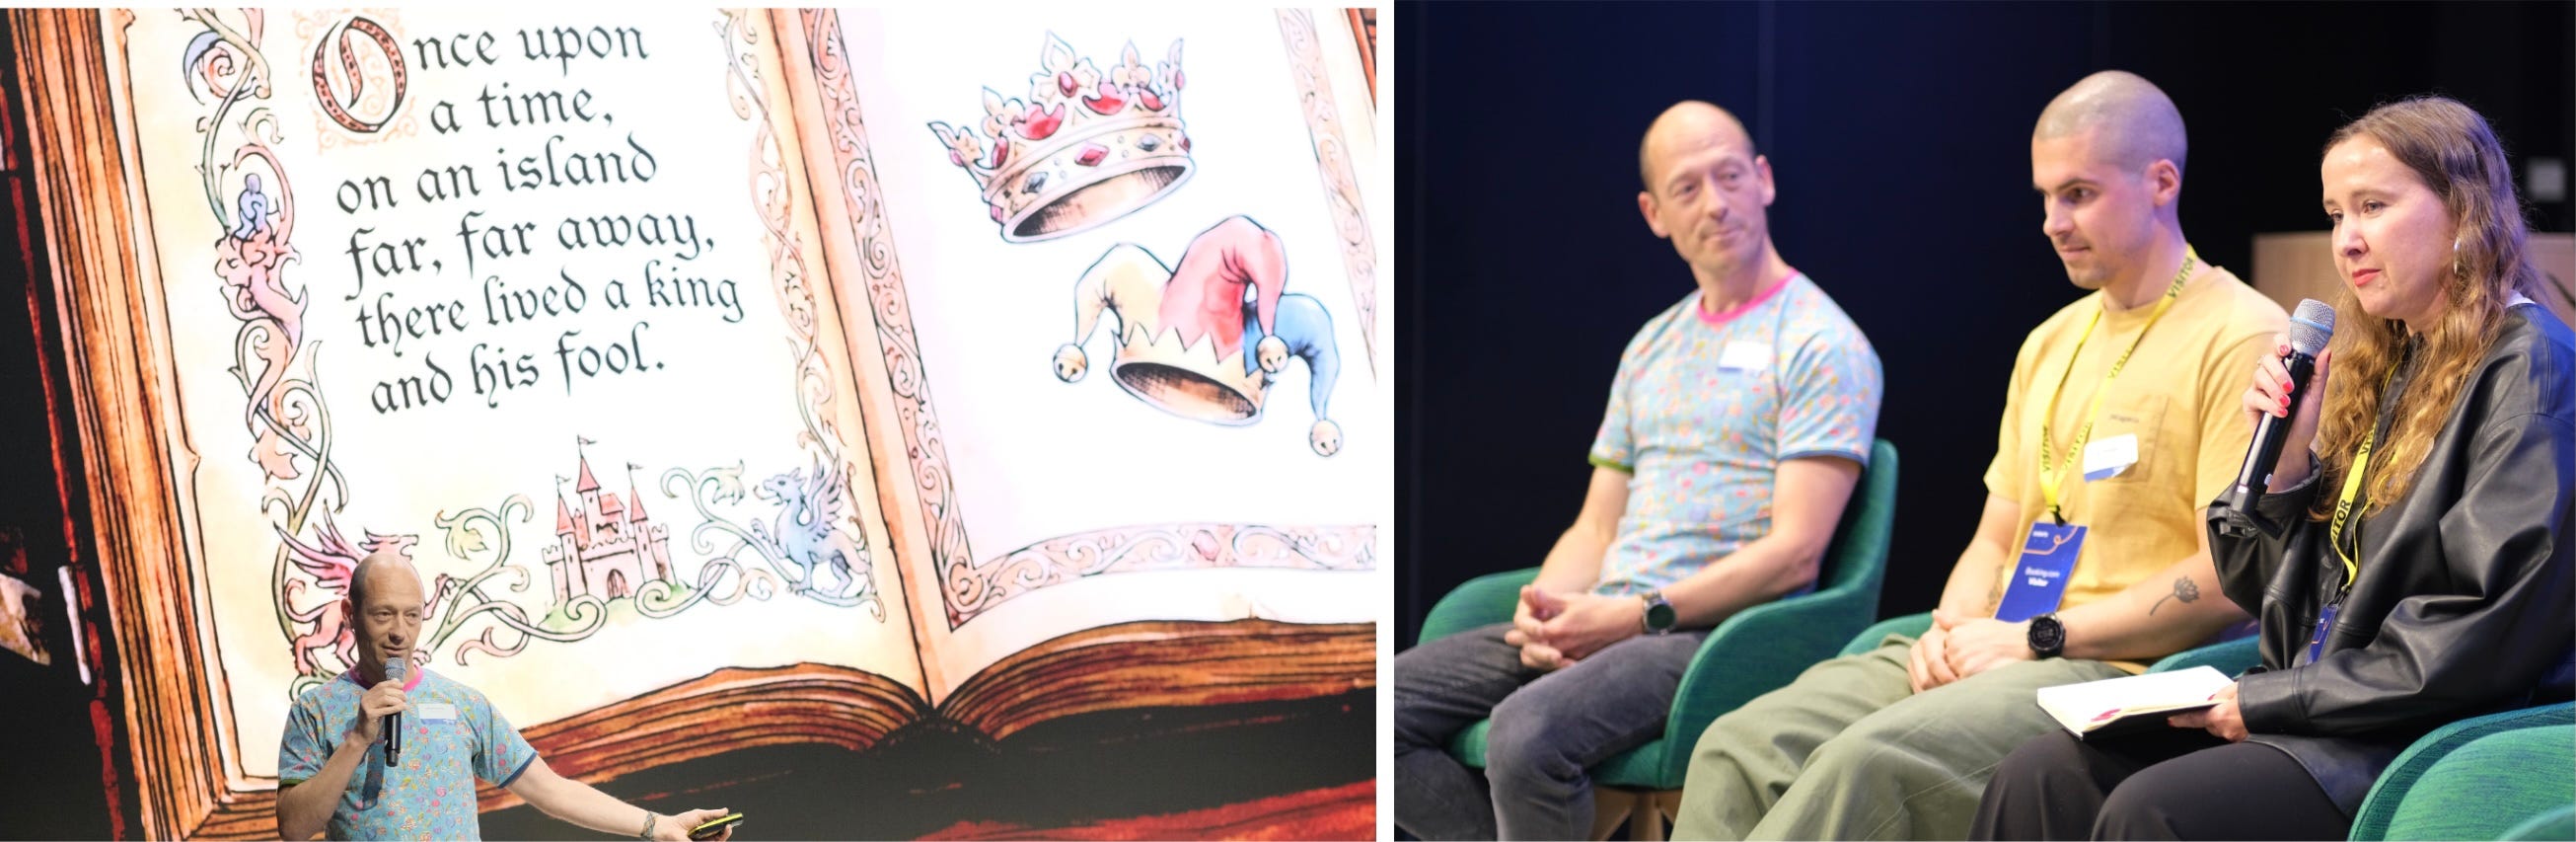
Lukas Vermeer, currently at VistaPrint and a long-time member of the experimentation community, gave the afternoon’s most theatrical talk, which was, by design, the point. His argument: data practitioners need to think of themselves as jesters, not kings. The jester’s privilege is to speak truth to power without losing his head, using story and humor as the vehicle. Because people hate being proved wrong, telling someone their experiment was badly designed lands differently as a metaphor or story than a direct statistical rebuke.
Lukas shared several stories from his playbook:
“Bear sign” for why you monitor experiments for danger even without a large enough sample size;
“The boy who cried type error” as a mnemonic for type I and type II errors that actually sticks; and
“The first pancake”, used at VistaPrint to normalise early failure and remove the ego from the learning process.
Stories serve three purposes beyond explanation:
they’re easier to remember than jargon,
they bypass ego without confrontation,
and over time they build a shared shorthand that becomes culture.
Key takeaway: Stories are not decoration. They’re how abstract methodology becomes shared intuition and how you correct behaviour without making enemies.
Tech and Stats Do Not Shape Culture — Jev Gamper
Jev Gamper of Vinted closed the talk sessions with a retrospective on what it took to scale experimentation culture from a tight-knit team of a few hundred to an organisation of 2,000. His honest summary: the technical work was the easy part.
As Vinted grew fourfold from 2021 onwards, every new hire brought their own context and biases. The objection “our domain is too unique to experiment” wasn’t a technical problem, it was a belief system that required updating. Education helped create a shared language but had a short lifetime: people returned to their desks and the pressure to ship overcame the lessons from the workshop. What eventually moved the needle was harder incentives: setting KRs around experiment velocity at the business unit level, getting the numbers into leadership monthlies, and eventually shifting to cumulative impact as the goal-setting metric. Not a perfect measure, but one that made the value of experimentation visible in the language leadership already spoke.
Key takeaway: Subtlety doesn’t scale. Qualitative agreements and culture manifestos fade when leadership changes. Structural incentives, however imperfect, outlast them.
Final thoughts
What doesn’t show up in a recap like this is all the conversations. The breakfast tables where practitioners compared platform architectures over coffee. The hallway exchange after the micro-conversion talk where three teams realised they had the same low-traffic problem. The panel moments where the room found itself in genuinely unresolved territory.
The future of experimentation isn’t only about running more experiments faster in order to make better product decisions. It’s about building the culture, tooling, and shared language that make trustworthy decisions the path of least resistance, for humans and AI alike. AI has made building easy, but building the right thing is still difficult. Humans in the loop are still needed for strategy, taste and judgement. And we believe that community events like this help to share and sharpen the human loop.
This article was originally published on the Booking.com Medium blog.

